Attribution Is a Credit Rule, Not Proof That an Ad Caused a Sale
October 18, 2026
What Makes a Laptop Suitable for Local AI? Start With the Workload
October 18, 2026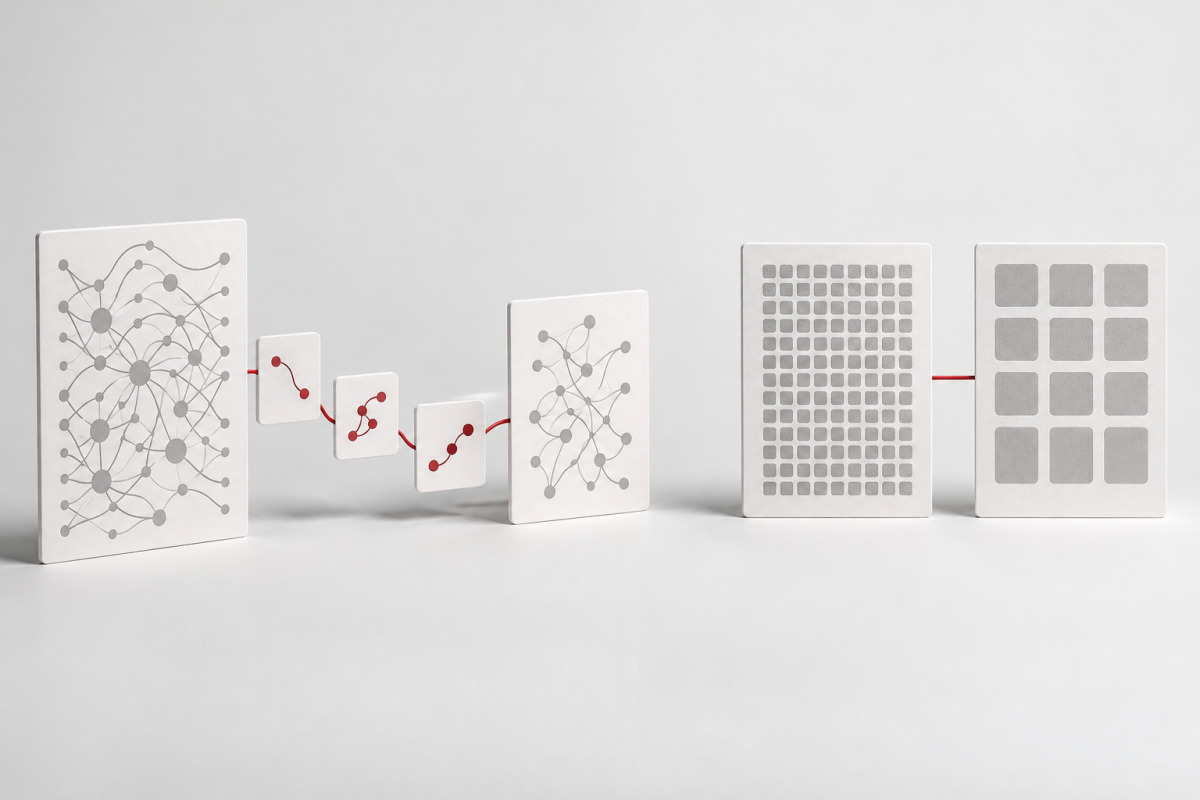
AI-generated conceptual illustration; no real models, training run or performance result is shown.
“Make the model cheaper” leaves the important question unanswered: which requirement should change, and what result must remain useful? Distillation and quantization can both appear in a deployment discussion, but they change different things. Separate the training relationship from the numerical representation before comparing a proposal’s memory requirements, preparation effort or behavior on the actual task.
Distillation trains a student using a teacher’s outputs
Distillation uses a teacher model’s outputs as a training signal for a student. In Distilling the Knowledge in a Neural Network, Hinton, Vinyals and Dean describe transferring knowledge from a cumbersome model or ensemble into a model more suitable for deployment. The student learns from that signal; it is not simply the teacher’s stored numbers rewritten with fewer bits.
The teacher’s output should not replace the task’s acceptance criteria. Define the behavior the student must preserve and evaluate it on representative cases, including difficult cases and known failures. A plausible response or similarity to a teacher on a few examples does not establish that the student retains every useful capability.
Quantization changes how numerical values are represented
Quantization uses lower-precision numerical representations, such as for model weights, to reduce memory requirements while aiming to retain useful quality. The Transformers quantization overview describes different methods, including approaches requiring calibration and approaches applied on the fly. This is a different mechanism from teaching a student to reproduce a teacher’s behavior.
Numerical precision still has to fit the software and workload. A format label alone does not establish that the intended runtime and hardware can use it efficiently. Quality also needs to be checked after a precision change. The existing hardware explanation connects these limits to model support, kernels and the application’s acceptable quality target.
Ask what the proposal actually changes
| Question | Distillation proposal | Quantization proposal |
|---|---|---|
| Primary mechanism | Train a student from teacher outputs | Change numerical representation |
| What to identify | Teacher, student and training signal | Model, precision and method |
| What to evaluate | Required student behavior on the task | Quality after the representation change |
| What the label cannot prove | Every teacher capability is retained | Every runtime becomes faster |
Compare two fictional proposals, not invented results
Imagine a fictional team that summarizes approved service documents. Proposal A trains a student using teacher-produced responses for that task. Proposal B keeps the existing model as its starting point and changes the representation of its weights. These are conceptual proposals; no model has been downloaded, trained, converted or tested in this example.
The team’s desired output is a concise summary that preserves the source’s scope and qualifications. An answer that omits a key exception is unacceptable even if it is shorter or appears sooner. The team would write that requirement before assigning either proposal a benefit. Neither proposal has an invented accuracy score, latency result or resource saving attached to it.
The two proposals also need distinguishable records. For A, identify which teacher, student, examples and output behavior the proposal concerns. For B, identify the original model, the proposed numerical representation and the intended software route. The purpose is to make the comparison reproducible in principle, not to claim that either path has already succeeded.
Memory and recurring work are separate parts of cost
Model weights are only part of the working set. Runtime state and the key-value cache also consume memory, and context length and concurrency matter. A smaller weight representation alone is not a complete memory budget for a serving workload. Keep the resource question tied to what the system must hold and do for the intended requests.
A useful proposal states which cost it seeks to change: preparation effort, storage, working memory, recurring inference work or reviewer effort. Those are separate questions. A reduction in one category should not silently be reported as a reduction in all of them. The fictional team has no measured resource data, so its brief can identify required evidence but cannot calculate savings.
For example, the fictional team might care more about fitting its approved workload into a particular deployment environment than about achieving the shortest possible response time. Another task might prioritize responsiveness. State the constraint directly, alongside the required output quality, so the evaluation can answer the actual question rather than reward a convenient but irrelevant number.
Compatibility and quality need their own evidence
For hardware and precision context, continue with AI Accelerators Beyond TOPS: Memory, Bandwidth and Real Workloads. It explains why memory movement, precision and the supported software path matter together. A generic compression label does not establish application throughput, and a documented method’s availability does not certify a particular deployment.
For evaluation, read How to Evaluate an AI Agent Before It Can Act. Keep a protected set of cases separate from the examples used to improve the candidate, and inspect important failures rather than relying on a single score. In the fictional summary task, that would include whether factual qualifications survive, not only whether the text looks fluent.
The evaluation record should name the exact candidate, task, software conditions and evidence scope. If a result is unknown, leave it unknown. When a change addresses a resource constraint but introduces a quality problem, report both. That gives the next reviewer a decision they can assess without treating a paper’s result or a library’s feature list as a firsthand test.
For the distinction between training and producing an answer, continue with What Happens Between Your Prompt and the Model’s Answer?. Here the useful contrast is narrower: one proposal trains a student from a teacher’s signal, while the other changes numerical representation. Each needs evidence that the resulting candidate remains suitable for its intended job.
A defensible comparison begins with the workload and ends with a bounded claim: what changed, which requirement it addressed, what quality was checked and what remains unproven. Distillation and quantization name mechanisms. They do not, by themselves, supply a universal promise about speed, size, cost or retained behavior.