Local AI Hardware: When an NPU Helps — and When You Still Need a GPU or Cloud
October 14, 2026
DGX Spark vs ZGX Nano vs Veriton GN100 vs Dell GB10 vs Mac Studio M5 Ultra
October 14, 2026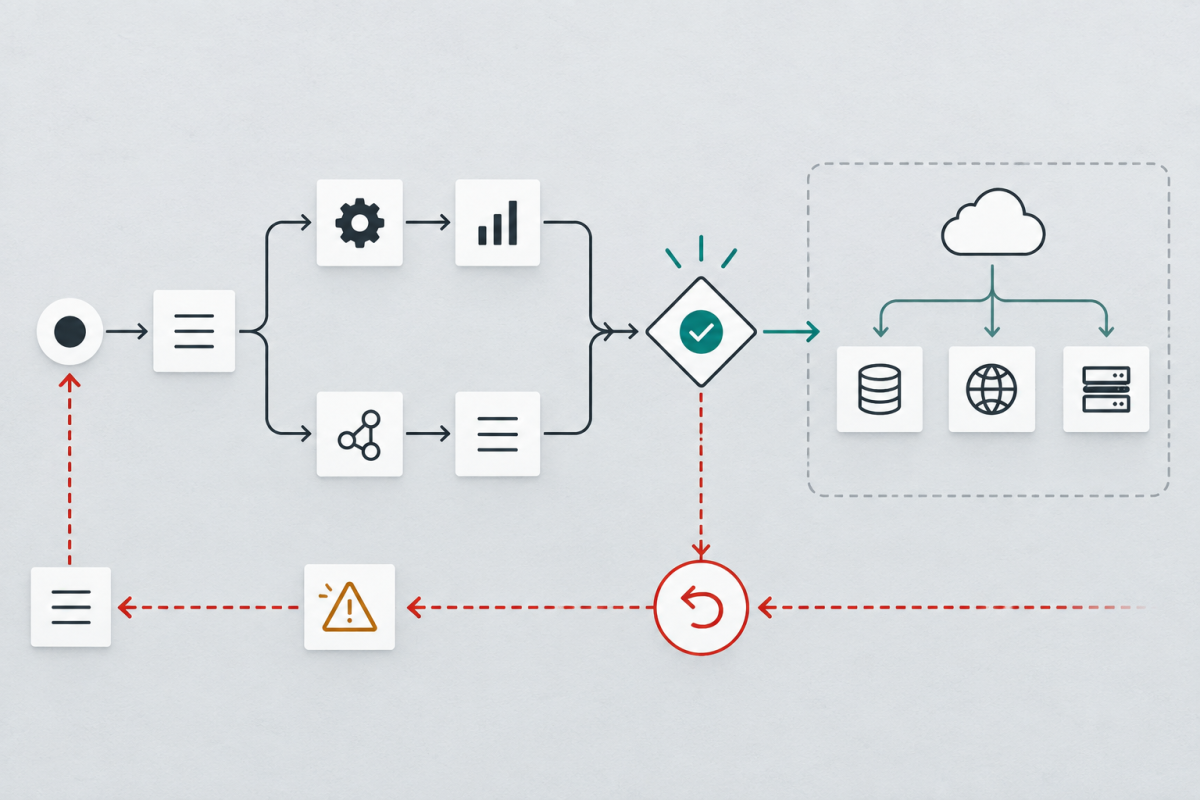
An AI agent can produce an excellent demonstration and still be unsafe for routine work. The demo proves that success is possible. Deployment requires evidence that the system succeeds often enough, fails visibly and respects its boundaries when the input is unfamiliar.
Evaluation should begin before the agent can change anything important. Start with the job, not the model. Define the user, input, expected output, allowed sources, tools, completion condition and consequences of a wrong action. A vague objective produces a vague test.
Establish a baseline
Measure the current non-agent process or the simplest deterministic alternative. The baseline may be manual work, a search form, a script or a read-only assistant. Without it, a team can spend heavily on autonomy without proving that the result is better.
Record quality, time, cost, review burden and failure recovery. The agent does not need to win every dimension, but the trade-off must be explicit.
Build a representative task set
A test set should include ordinary work, edge cases and known failures. Include incomplete inputs, contradictory instructions, unavailable tools, stale sources and requests that must be refused or escalated. Separate the cases intended to improve from the cases that must not regress.
Do not build the entire set from examples already used to tune the prompt. Keep a protected evaluation slice so changes can be tested against material the system has not been optimized to memorize.
Inspect the trajectory
The final answer is only one output of an agent. The path may include searches, tool calls, handoffs, retries and approvals. OpenAI’s agent-evaluation guidance uses traces to capture these steps and graders to ask structured questions: Was the correct tool selected? Were arguments valid? Did the handoff occur at the right time? Was a safety rule violated?
Trajectory review reveals failures hidden by a plausible final response. An agent may reach the right number from the wrong source or complete a task only after several dangerous actions that happened not to cause damage in the test environment.
Plausibility, source support and a test result differ
Fluent wording is not evidence. A hallucination can sound plausible while making a factually incorrect assertion. Check the claim against the task’s permitted evidence; an attached link alone does not show that its source supports the claim and its qualifications.
Groundedness asks whether claims are supported by specified references. Google’s grounding documentation evaluates a candidate against supplied reference texts. That is a relationship to those references, not a certificate that they are current or authoritative. Preserve source dates and qualifications when judging an answer.
In a fictional test, an archived service guide says “opens Monday,” but the question requires current opening information. Repeating that line may be supported by the archive while failing the freshness criterion. It does not establish that Monday is now false; the current answer remains unverified. Record claim support, source date and the failed or unresolved task criterion separately. An evaluation result applies to its stated cases and criteria; it is not a universal certificate.
Use automatic graders carefully
Rule-based checks work well for schemas, exact fields, files, status codes and other objective conditions. Model graders can help evaluate style, relevance or complex behavior, but they introduce another probabilistic system. Calibrate them against human-reviewed examples, test disagreement and avoid treating a single score as ground truth.
For high-impact workflows, combine deterministic checks, model-assisted review and human spot checks. NIST’s AI risk resources frame testing, evaluation, verification and validation as lifecycle activities rather than a one-time launch gate.
Test safety and recovery
Capability testing asks whether the agent can complete the job. Safety testing asks whether it stays within its authority. Include prompt injection, malicious documents, excessive tool arguments, repeated failures and unavailable dependencies. Verify that the agent stops, asks for approval or hands control back when required.
Rollback also needs a test. A documented rollback that has never been exercised is an assumption. In staging, confirm that actions leave an audit record and can be reversed without damaging unrelated state.
Expand authority in stages
A practical sequence is:
- offline evaluation with fixed examples;
- read-only use against current data;
- shadow mode beside the real process;
- bounded staging actions with approval;
- narrow production actions with monitoring and rollback;
- broader authority only after new evidence supports it.
Each stage should have stop conditions. More autonomy is not the default reward for passing once.
Keep evaluation alive
Models, prompts, tools, prices and source data change. Add verified failures to the test set. Re-run retention cases after every meaningful change. Track quality, safety, latency and cost together so an apparent improvement does not hide a regression elsewhere.
The most useful evaluation question is not “Did the agent look intelligent?” It is “Do we have enough evidence to trust this exact system with this exact action?”
For the implementation sequence, read From AI Demo to Reliable Workflow. For authority design, continue with AI Agent Safety.
Primary sources
- OpenAI: Evaluate agent workflows
- OpenAI: Testing agent skills systematically with evals
- NIST AI Resource Center
- NIST Generative AI Profile
Source and adaptation note: This article draws on evaluation concepts in AI Agents in Depth: Design Principles and Engineering Practice by Bojie Li and contributors, distributed under Apache License 2.0, and on the cited primary sources. It was independently rewritten, reorganized and expanded for Stariy.com.