MCP Is Becoming Infrastructure: What the 2026 Specification Changes
October 14, 2026
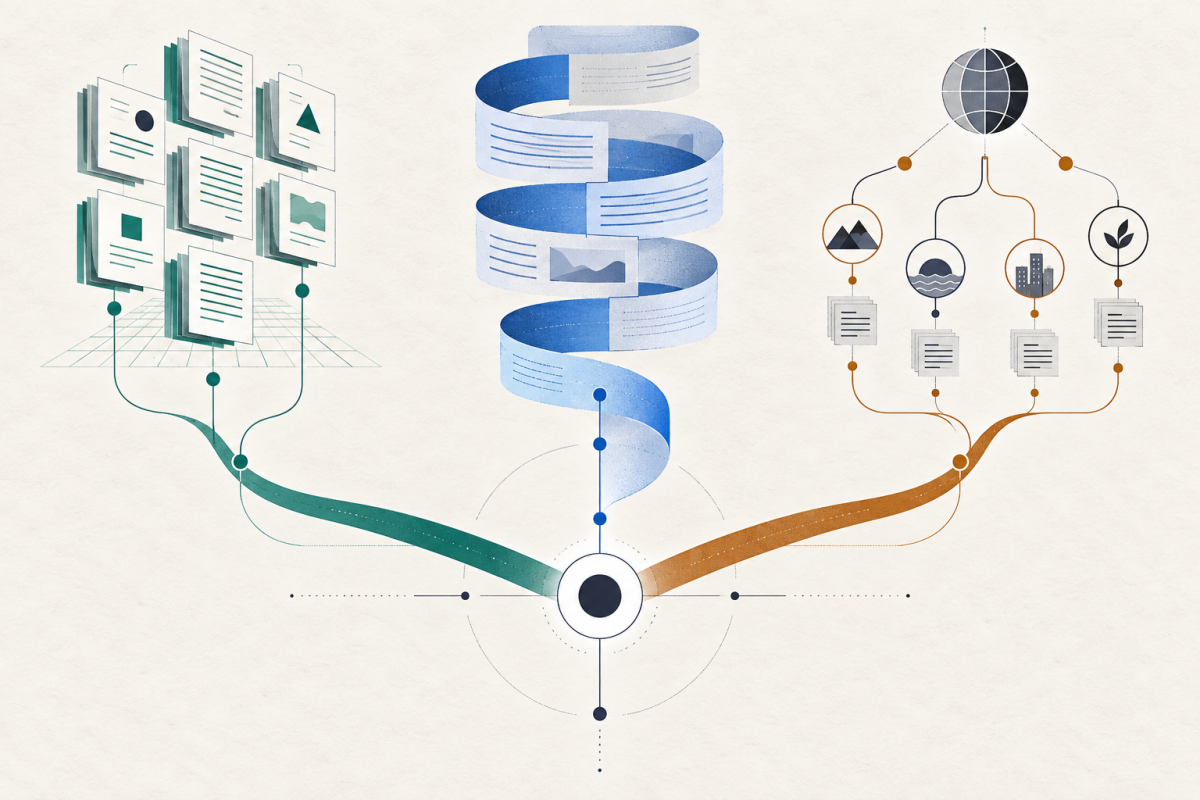
Prompting vs RAG vs fine-tuning is a choice between methods that address different problems, not a ladder of maturity. RAG means retrieval-augmented generation. The methods can be used together when each addresses a measured failure.
Prompting changes the task definition
Use prompts to clarify the goal, constraints, output format, tool guidance and examples. Prompting is the fastest lever when the model misunderstands the assignment, omits required structure or needs a small number of demonstrations.
It does not reliably supply changing external facts. Adding a current policy to one enormous system prompt also makes maintenance difficult.
Build a bounded task with examples
For a fictional task, replace “tell me the status” with “Using only the supplied delivery note, return pending or confirmed; do not add facts.” Here, pending means the note does not state confirmation. The two input–output demonstrations below are few-shot prompting: examples supplied in context, not a parameter-training run.
| Invented note supplied as data | Desired label |
|---|---|
| Delivery planned; confirmation pending. | pending |
| Delivery confirmed. | confirmed |
Separate reusable application guidance from the individual task. Google’s prompting guide distinguishes system instructions from task input and context. A system instruction can guide role, style or constraints; use the platform’s documented mechanism, since roles and precedence differ. A label inside ordinary task text does not itself configure that mechanism. Guidance does not replace access controls or guarantee accuracy.
Keep separate check cases, such as the invented note “Date proposed; confirmation missing.” Check whether the answer preserves that uncertainty, then compare revisions on the same cases. The prompt-to-answer walkthrough illustrates why a plausible response still needs checking against its supplied evidence.
RAG supplies external knowledge
Retrieval is appropriate when the answer depends on private, current or source-specific information. The system searches an approved corpus and adds relevant material to context. This supports citations and updates without retraining the model.
RAG can fail before generation begins: poor chunking, missing metadata, stale indexes or the wrong query can hide the needed evidence. Evaluate retrieval separately from answer quality.
Fine-tuning changes model behavior
Fine-tuning uses training examples to make a model more consistent at a task, format or style. OpenAI’s optimization guidance recommends evaluation first and emphasizes representative training and hold-out test sets. Fine-tuning is not a database update. It is a poor way to inject facts that change frequently or must be cited precisely.
Product availability also changes. OpenAI’s current documentation notes transitions in its own fine-tuning platform, which is a reminder to verify provider-specific support at implementation time rather than embedding product assumptions in a permanent architecture.
Prompting vs RAG vs fine-tuning: a decision matrix
| Failure | First lever |
|---|---|
| The model misunderstands instructions | Prompt and examples |
| The model lacks current or private facts | Retrieval/RAG |
| Output format or behavior is inconsistent at scale | Fine-tuning after evals |
| Tool arguments are unsafe | Schema validation and code, not training alone |
| Source selection is wrong | Retrieval and ranking evaluation |
Combine levers deliberately
A support agent may use a prompt for role and escalation, RAG for current policy and a fine-tuned smaller model for consistent classification. The architecture is justified only if each component addresses a measured error.
To choose prompting vs RAG vs fine-tuning, start with an evaluation set and the simplest prompt. Add retrieval when failures are caused by missing knowledge. Consider fine-tuning when enough high-quality examples exist and behavior remains inconsistent. Re-run the same evaluation after each change.
When none is enough
Deterministic business rules, permissions and calculations belong in code. No optimization method should be trusted to enforce an exact monetary limit or access-control rule without an external validator.
Continue with RAG vs Long Context vs Search, Context Engineering and How to Evaluate an AI Agent.
Primary sources
- OpenAI: Optimizing LLM accuracy
- OpenAI: Model optimization
- OpenAI: Fine-tuning best practices
- OpenAI: Retrieval
Adaptation note: This article was informed by knowledge, context and post-training concepts in AI Agents in Depth: Design Principles and Engineering Practice by Bojie Li and contributors, Apache License 2.0. It was independently structured and updated with current primary documentation.
For the retrieval step itself, follow how a document becomes a useful passage through chunking, candidate selection and evidence checks.