Why the Highest Bid Does Not Simply Win an Ad Auction
October 17, 2026
API, JSON and Webhooks: Follow One Event Between Two Applications
October 18, 2026
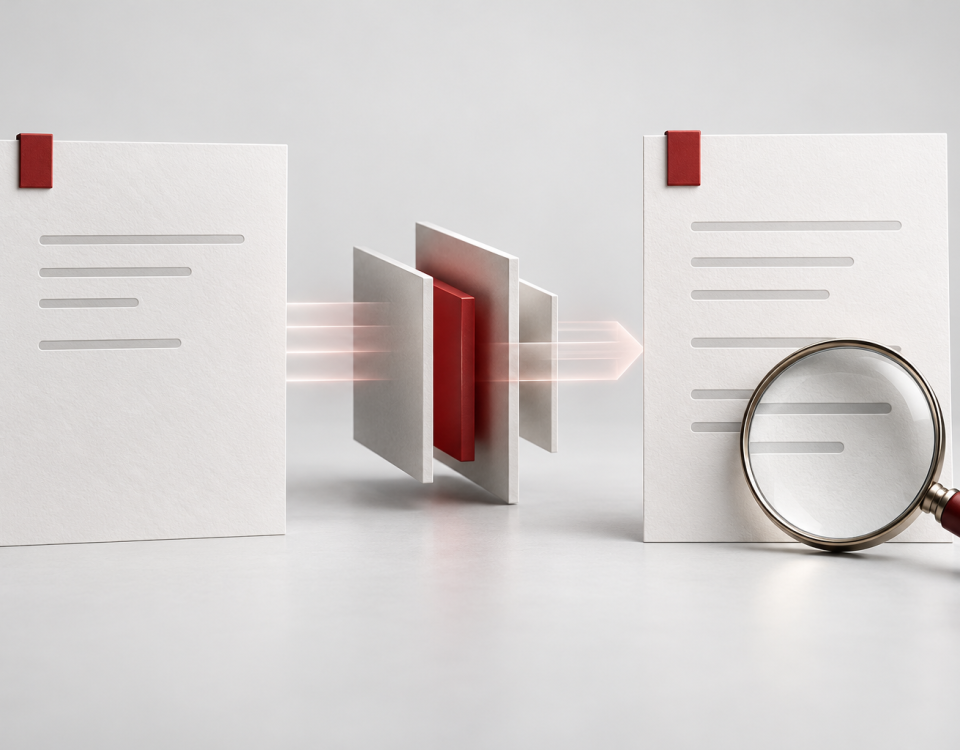
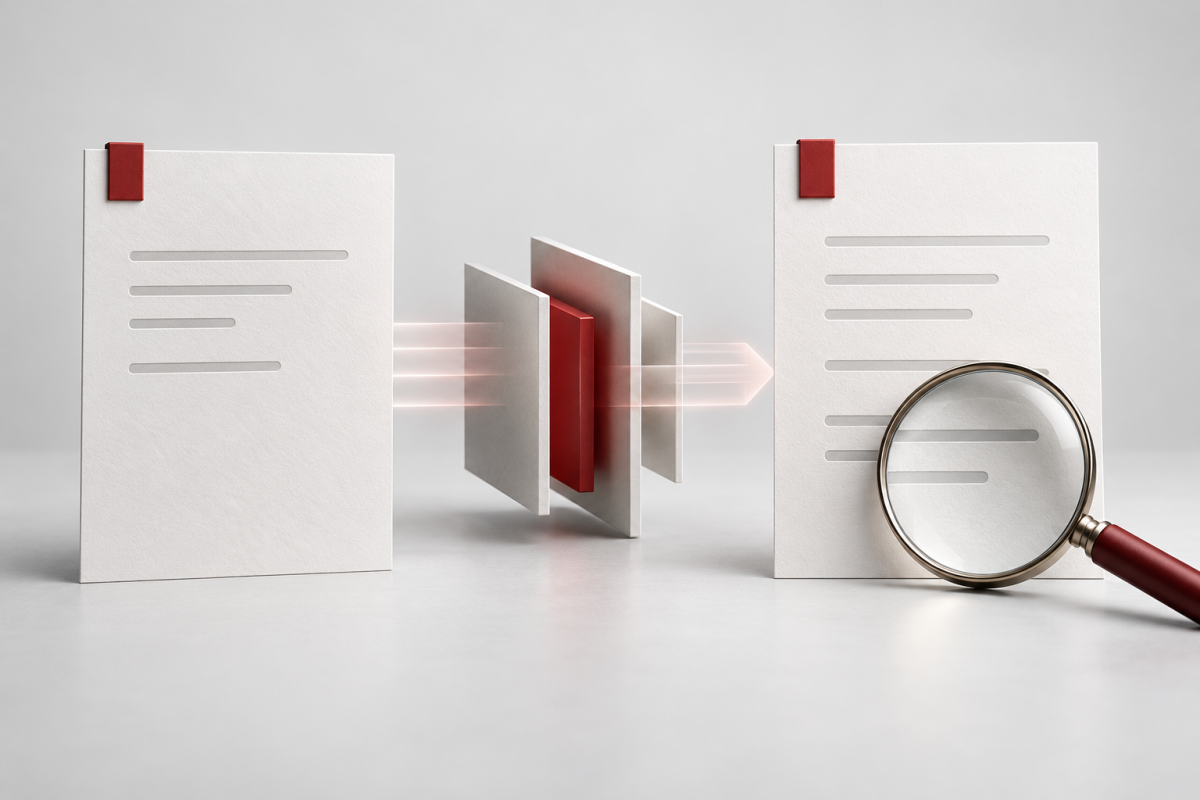
Relevant passages need their context. AI-generated illustration.
A system can search the right collection and still supply the wrong passage to the component writing an answer. The important question is not just whether a document was found, but whether the selected text preserves the evidence needed for this request. Follow that question through the retrieval pipeline before blaming the final wording.
Begin with a question and the passage that would answer it
Consider a fictional equipment-loan guide. Its “Equipment loans” section says: “Extensions require coordinator approval before the existing due date. Equipment reserved for another booking cannot be extended.” A reader asks, “Can I keep the borrowed projector longer?” The guide, question and all candidate passages below are invented; no retrieval system has been run for this example.
A useful answer would need both the approval condition and the reservation exception. A passage about extending room bookings could resemble the question while addressing a different object. Before choosing a search method, the example gives us a concrete relevance test: does the selected evidence answer this equipment-loan question without losing its qualification?
Choose boundaries that keep the needed context together
Chunking divides material into smaller units for processing and retrieval. Microsoft’s chunking guidance discusses fixed-size and structure-aware approaches, including boundaries based on sentences or headings. It also explains that overlap can preserve continuity while duplicating some content. The useful choice depends on the documents and questions; one size or overlap is not a universal setting.
In our fictional guide, splitting immediately before the reservation exception could leave the approval sentence looking sufficient on its own. Keeping the section heading and both conditions together would be a candidate design to evaluate. It is not a measured improvement. We would inspect the resulting passages before claiming that a different split solved the problem.
The team in this example also proposes retaining a link to the parent guide and its version with each passage. These are provenance and eligibility checks, rather than information a similarity score can establish. The fictional collection could contain a relevant-looking passage that is outdated or unavailable to the person asking; that still needs separate handling.
Represent the question and search for candidates
An embedding represents data as a numerical vector. Google’s teaching material explains how positions in an embedding space can capture relationships, while warning that the representation may not be readily interpretable. An embedding is not a readable summary or a certificate that a passage is true.
Vector search compares representations to retrieve similar items. Google’s BigQuery overview describes finding semantically related items through distances in embedding space. For a document question, this supports selecting candidate passages; it does not establish that every selected passage contains the answer or that the required source was retrieved.
Semantic search describes the aim of matching meaning or concepts, beyond literal wording. Microsoft’s vector-search overview illustrates this distinction and describes Azure’s hybrid combination of vector and keyword search. These are related ideas: meaning-oriented retrieval is a goal, while vector comparison is an approach that can contribute to it.
Our reader says “keep longer,” while the imaginary guide says “extensions.” A meaning-oriented match might help bridge that wording difference. It might also return the room-booking passage. We have not calculated embeddings, scores or a threshold, so these are possibilities to test, not claims about the order a real system would return.
Rerank the passages that actually reached the candidate set
Reranking applies an additional relevance assessment to retrieved candidates. Google’s ranking documentation describes taking a query and records already found by a search method, then reordering them for relevance. This is a second assessment of the supplied set, not a guarantee about the collection as a whole.
Suppose our hypothetical candidate set includes the complete equipment-loan section and a room-booking passage. A proposed reranking check would ask which one better addresses the projector question. If the reservation exception never reached the candidate set, however, reordering that set could not restore it. The investigation would need to return to indexing, boundaries or initial retrieval.
| Checkpoint in the fictional case | Evidence to inspect | Conclusion to avoid |
|---|---|---|
| Passage boundaries | Approval condition and exception remain together | Every short chunk is adequate |
| Initial candidates | Equipment-loan evidence is included | A similar topic proves the answer |
| Reranked selection | The relevant supplied passage is retained | A missing source was recovered |
| Final answer | Both conditions are preserved and supported | Readable wording proves correctness |
Evaluate retrieval and the answer as separate stages
The fictional team can first review whether the required passage was available, retrieved and retained after reranking. It can then review whether the answer uses that passage faithfully. Those checks diagnose different gaps. A correct passage followed by an unsupported answer calls for a different investigation from an answer written without the necessary passage.
For example, “Yes, coordinator approval is enough” would drop the reservation exception. That sentence is an author-written counterexample, not a generated result. A supported explanation would preserve the conditions rather than promise an extension. If the available evidence is incomplete, the review should record that gap instead of inventing the missing rule.
If the broader question is whether the failure calls for a better prompt, retrieval or model adaptation, Prompting vs RAG vs Fine-Tuning provides that decision framework. Here the narrower task is to inspect how a document becomes usable evidence. Preserve the source context, distinguish candidate relevance from factual support and evaluate the answer against what the passages actually say.