From a Valuable Action to a Measured Conversion
October 17, 2026
What Happens Between Your Prompt and the Model’s Answer?
October 17, 2026
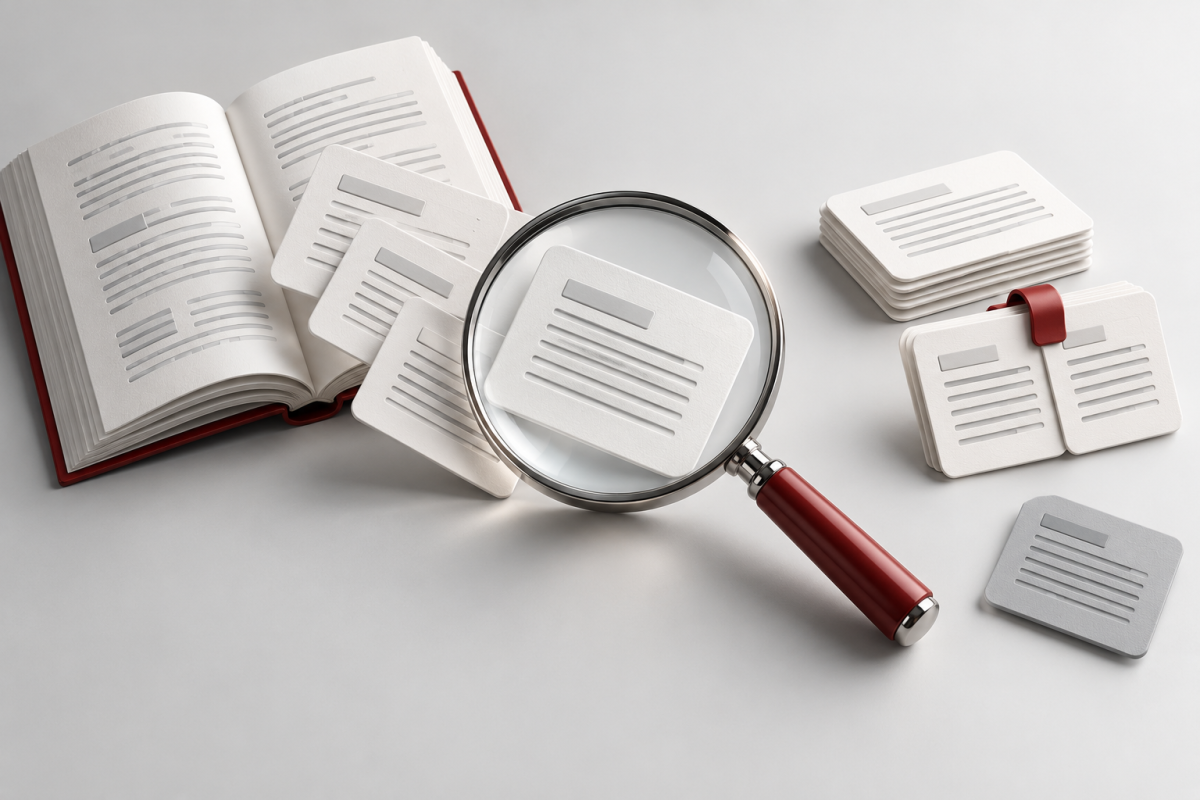
From labeled examples to a suggested category. AI-generated illustration.
A request arrives: “I need to move my appointment.” A system suggests sending it to the scheduling team. What produced that suggestion: a written rule, a learned pattern or a generated explanation? The answer matters when deciding what to check and what the system should be allowed to do.
AI describes the field; machine learning describes an approach
Artificial intelligence, or AI, covers technologies for tasks associated with intelligence, including interpreting language and making predictions. Machine learning, or ML, is an approach within that broader field. Google Cloud’s comparison of AI and ML makes the distinction in scope; the terms do not name interchangeable products.
In machine learning, training uses data to produce a model that can make predictions or generate content. In supervised learning, examples include the answers the model is meant to learn to predict. A classifier addresses a category question, rather than necessarily producing a written response.
An instruction such as “send every form marked scheduling to the scheduling team” can be a fixed rule. Its automation alone does not demonstrate learning from examples. Conversely, calling an application AI tells us little about whether its particular routing decision is suitable. Inspect how the task is actually performed.
Give the model a task and the data a meaning
A dataset is a collection of data. In a learning task, distinguish the examples used for training from those reserved for evaluation. The model, in the ML sense used here, combines learned values and structure to turn supplied inputs into predictions.
Consider one fictional request classifier. Its designers invent three destination labels: scheduling, billing and technical support. Each teaching example pairs a request with its intended destination. The entire scenario is illustrative: no customer messages, deployed model, training run or measured result from this website is represented.
Before collecting examples, the fictional team needs a labeling convention. A request to change an appointment belongs to scheduling; a question about an invoice belongs to billing. A message containing both requires an agreed treatment. That decision defines the teaching task rather than something a dataset’s file format can settle.
The team proposes including varied wording and cases its reviewers find ambiguous. It also proposes reviewing whether labels consistently reflect the intended destinations. These are checks to perform, not claims that the imaginary dataset is representative or that a larger collection would automatically solve its weaknesses.
Training changes learned values; inference applies them
Model parameters are learned values, such as weights and biases. Training adjusts those values using examples. They are distinct from the request supplied as input. Google’s ML glossary calls applying a trained model to make a prediction inference.
| Part of the fictional system | Its role here | What to keep distinct |
|---|---|---|
| Labeled request collection | Supplies examples and intended destinations | Examples versus evidence of successful performance |
| Training step | Fits a model to the teaching task | Learning a model versus handling a new request |
| Trained classifier | Suggests a destination for a new request | Predicted category versus a verified decision |
| Surrounding application | Shows the suggestion to a reviewer | Model output versus permission to route work |
Suppose the team then uses a fixed trained version for suggestions. A new request is input to that version, not a new parameter. Processing it does not, in this deliberately fixed setup, update the learned values. Whether another application separately collects feedback or retrains is a different design question.
Now imagine a request that says both “move my appointment” and “the invoice looks wrong.” The classifier might suggest one category while the reviewer sees two tasks. The fictional team would need to decide how to handle that mismatch. The output is a suggestion within the task it defined, not proof that the request has only one valid interpretation.
For an evaluation, the team proposes holding out requests that were not used to fit the model and comparing suggestions with reviewed destinations. It would inspect mistakes by category and decide which errors require human review. Until that work exists, this example supports an explanation of the process, not an accuracy or time-saving claim.
Parameter count can describe model capacity, but it does not establish quality for this routing task. A claim that one candidate is better needs relevant evaluation evidence. Dataset fit, learned model and actual use remain separate questions.
Generating a reply is another output task
Generative AI creates content from learned patterns. Google Cloud describes outputs such as text, images and code. This capability does not specify one architecture, and a generated explanation is a different output from a destination label. Both can be parts of a larger AI application.
Google’s introduction to ML includes both prediction and generation. A model can categorize an input, while a generative model can produce content from it. The distinction is about the task and output; a chat interface alone does not explain what learning occurred or what evaluation would establish usefulness.
Returning to the same fictional request, the team could ask a separate generative component to draft a reply after a reviewer resolves the destination. The draft might propose an appointment change, but it would not establish that any appointment was actually changed. The application would still need verified information and authority for that action.
A fluent draft also cannot provide missing evidence about the invoice. In this scenario, the sensible review question is whether the reply matches confirmed facts and the decision the reviewer made. Describing the component as generative does not remove that need.
When examining an AI system, ask which data shaped the task, which trained model is being used, what input it receives now and what happens after its output. Those questions connect the vocabulary to an inspectable decision, instead of treating the word AI as an explanation.
Next, follow what happens between your prompt and the model’s answer to connect these ideas to a concrete input and a proposed response.